Optimization
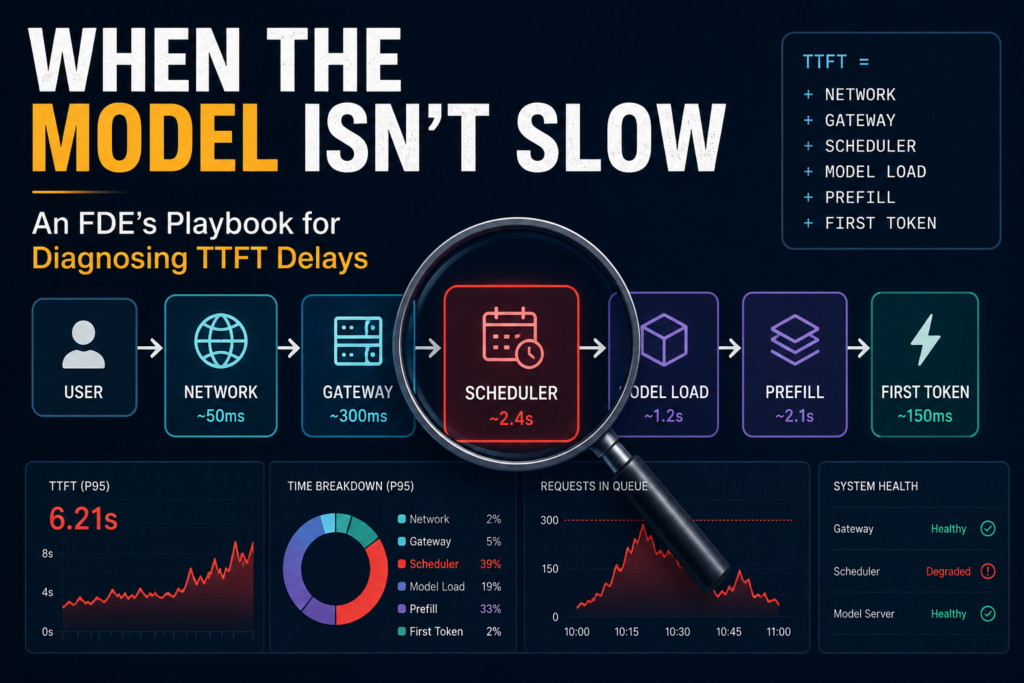
An FDE’s playbook for diagnosing TTFT delays
Most discussions about AI inference performance focus on model speed. In practice, however, users experience performance through a different metric: Time to…
OPEN PRACTITIONER COMMUNITY
Learn to serve, scale, and optimize AI inference. Share practical knowledge with the engineers, researchers, and operators building production systems.
Learn. Connect. Contribute.
CONNECT & LEARN
UPCOMING EVENT
Oct 24, 2026 · IIT Bombay
Join us for Mumbai’s first-ever vLLM and llm-d AI Inference Meetup, where we explore the architecture, performance optimizations, and engineering behind scalable, high-performance AI inference.
View event →
KNOWLEDGE FROM THE FIELD
Technical deep dives and lessons from real inference systems.
Optimization
Most discussions about AI inference performance focus on model speed. In practice, however, users experience performance through a different metric: Time to…
Cost Per Token
As enterprises move from experimental AI deployments to large-scale production, a stark reality has emerged: inference—specifically, simply throwing larger models at…
Inference Architecture
NVIDIA Blackwell and NVFP4 fundamentally change the economics of LLM inference by dramatically increasing effective HBM capacity and enabling much higher…
Six operating dimensions. Fifteen practices. A shared way to reason about production inference.
Choose the right models, infrastructure, and tooling.
Deploy and scale production inference workloads.
Direct requests across models and infrastructure.
Understand latency, quality, reliability, and cost.
Improve throughput, GPU utilization, and efficiency.
Build secure, accountable, and reliable systems.
JOIN THE COMMUNITY
Open knowledge. Real-world experience. Better production systems.